pi-llama-skip-reasoning
Force the model to answer or act right now skipping any more reasoning
Package details
Install pi-llama-skip-reasoning from npm and Pi will load the resources declared by the package manifest.
$ pi install npm:pi-llama-skip-reasoning- Package
pi-llama-skip-reasoning- Version
0.1.0- Published
- Oct 1, 2026
- Downloads
- not available
- Author
- ea_man
- License
- MIT
- Types
- extension
- Size
- 121.9 KB
- Dependencies
- 0 dependencies · 1 peer
Pi manifest JSON
{
  "image": "https://store.piffa.net/lm/qwen_slap.jpg",
  "extensions": [
    "./extensions"
  ]
}
Security note
Pi packages can execute code and influence agent behavior. Review the source before installing third-party packages.
README
pi-llama-skip-reasoning
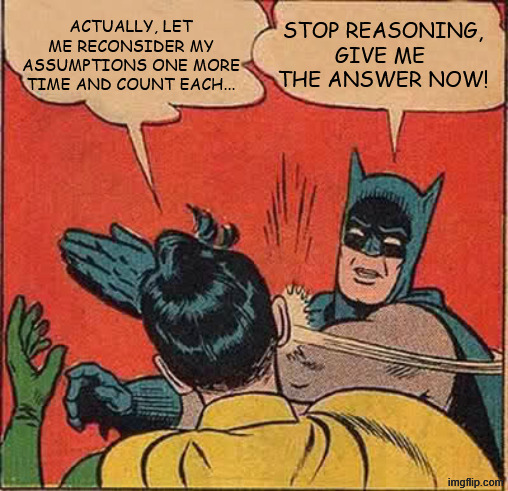
A Pi extension that adds a hotkey to force your local llama.cpp model to stop reasoning and produce the answer / action immediately — without aborting the request, losing any context, or invalidating the KV cache.
While the model is streaming a thinking block, the footer shows:
reasoning... (alt+t to skip reasoning and provide answer now)Press the hotkey (or run /skip-reasoning) and the model emits its
reasoning-end sequence right away and writes its normal answer. KV cache,
conversation state, and the running completion are all preserved — nothing is
cancelled or recreated.
Requirements
- This uses llama.cpp's native real-time reasoning interruption, added
upstream in PR #23971
(merged 2026-06-02) — the same feature behind the "Skip reasoning" button
in the llama.cpp WebUI. If your WebUI shows that button, your build
supports this extension. On older builds the control endpoint is absent, the
hotkey reports
skip-reasoning failed: ... HTTP 404, and nothing else about your setup changes. - A
llama-serverreachable from the machine running Pi (default:http://127.0.0.1:8080, or thebaseUrlof your provider in~/.pi/agent/models.json). - The model should have reasoning enabled (e.g.
--reasoningon llama-server, or a thinking-enabled chat template). The hotkey is a graceful no-op when the model is not currently reasoning.
Install
# from a local checkout
pi install ./pi-llama-skip-reasoning

# or from npm
pi install npm:pi-llama-skip-reasoning
If you previously used the standalone
~/.pi/agent/extensions/llama-skip-reasoning.tsfile, remove it before installing the package to avoid double registration.
Usage
| Trigger | Action |
|---|---|
alt+t (default) |
Force reasoning end on the active completion |
/skip-reasoning |
Same, as a command |
Feedback:
skip-reasoning: reasoning end forced, model continues to the answer— success.skip-reasoning: model not currently reasoning— pressed, but nothing to force.skip-reasoning: no active llama.cpp completion to control— pressed between turns.skip-reasoning failed: ...— server unreachable, or a llama-server build without PR #23971 (the control endpoint 404s).
How it works
- For every chat completion sent to your configured provider, the extension
injects
"reasoning_control": trueinto the request. This arms llama.cpp's reasoning-budget sampler for that slot so it can be forced mid-generation. - The streamed chunk
id(chatcmpl-...) is tracked from the assistant message (responseId). - On hotkey press the extension fires (non-blocking):
POST {baseUrl}/chat/completions/control { "id": "<chatcmpl id>", "action": "reasoning_end" } - llama-server routes the control task to the live slot and calls
common_sampler_reasoning_budget_force(). The sampler masks all logits except the model's own chat-template reasoning-end sequence (nothing is hard-coded), the tag is emitted, and generation continues into the answer.
The same endpoint is used by the "Skip reasoning" button in the llama.cpp WebUI.
Configuration
Optional file ~/.pi/agent/llama-skip-reasoning.json (all keys optional):
{
  "key": "alt+t",
  "provider": "llama",
  "controlUrl": "http://127.0.0.1:8080/v1/chat/completions/control"
}| Key | Default | Meaning |
|---|---|---|
key |
alt+t |
Hotkey. Extension shortcuts can't be remapped in Pi's keybindings.json, so this file is the override point (e.g. if your terminal grabs alt+t). An unknown modifier or malformed key is ignored with a warning, and alt+t is used. |
provider |
llama |
The provider id in ~/.pi/agent/models.json that points at your llama-server. Matched case-insensitively. |
controlUrl |
derived from the provider's baseUrl |
Full URL of the control endpoint; use only if your server lives elsewhere. |
After editing the file, run /reload in Pi.
If the control URL can't be derived (no such provider in models.json, or the
file can't be read), the extension logs a warning at load and falls back to
http://127.0.0.1:8080/v1/chat/completions/control.
Notes
- The hotkey targets the most recent completion of the configured provider — i.e. the one currently streaming. The id is dropped when that message ends, so pressing between turns reports "no active completion" instead of sending a stale id.
- Qwen3-style models may occasionally open a short second thinking block after a forced end before starting the answer; this is normal model behavior.
- Server-side log line (INFO, with
--log-verbosity 4):control reasoning_end: forced end of reasoning ... (cmpl_id=...).
License
MIT