@loka1/pi-auto-compact
Automatically compacts pi's context when it drops to a configurable percentage remaining, settable globally or per model, with a live status-bar indicator.
Package details
Install @loka1/pi-auto-compact from npm and Pi will load the resources declared by the package manifest.
$ pi install npm:@loka1/pi-auto-compact- Package
@loka1/pi-auto-compact- Version
0.3.2- Published
- Sep 16, 2026
- Downloads
- 316/mo · 16/wk
- Author
- loka1
- License
- MIT
- Types
- extension
- Size
- 44.8 KB
- Dependencies
- 0 dependencies · 1 peer
Pi manifest JSON
{
  "image": "https://raw.githubusercontent.com/loka1/pi-auto-compact/main/assets/preview.png",
  "extensions": [
    "./extensions"
  ]
}
Security note
Pi packages can execute code and influence agent behavior. Review the source before installing third-party packages.
README
pi-auto-compact
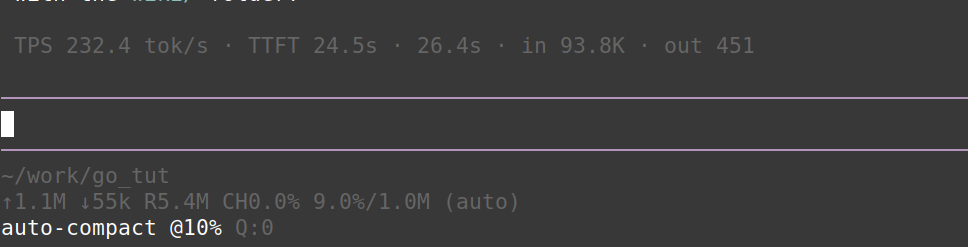
A pi extension that automatically compacts the conversation context when it reaches a configurable percentage of the context window used (default 80%).
The limit can be set globally (all models) or per model, and a footer status bar shows the active limit.
Features
- Auto-compaction fires when context usage reaches your threshold — keeps the context small and predictable.
- Global or per-model limits: set one default for everything, then override specific models by
provider/idor bareid. - Live status bar:
auto-compact @20% usedshows the active limit, updated every turn and on model change. - Easy commands to view and change the limit on the fly.
Install
As a package (from git or npm):
pi install git:github.com/loka1/pi-auto-compact
# or
pi install npm:@loka1/pi-auto-compact
Or drop the file at ~/.pi/agent/extensions/ (global) / .pi/extensions/ (project-local) and /reload.
Configuration
Config is merged from JSON files (project wins over global), or set interactively:
| File | Scope |
|---|---|
~/.pi/agent/auto-compact.json |
Global |
.pi/auto-compact.json |
Project-local (wins) |
{
  "enabled": true,
  "compactAtPercent": 20,
  "cooldownTurns": 1,
  "continueAfterCompact": true,
  "continuePrompt": "Context was automatically compacted. Continue the task you were working on...",
  "models": {
    "deepseek/deepseek-v4-pro": 15,
    "gpt-4o": 25
  }
}
compactAtPercent— global default: compact when this % of the context window is used (20 = compact when 20% used; higher = wait longer, lower = compact sooner).models— per-model overrides (win over global). Key by"provider/id"or bare"id".cooldownTurns— minimum turns between automatic compactions.continueAfterCompact— resume the agent after auto-compaction (defaulttrue).continuePrompt— the message sent to resume work after compaction.
Resume after compaction
pi's manual compaction API (ctx.compact()) aborts the running turn and does not resume it.
Without help, the agent stops right after an auto-compaction (you'll see an aborted tool
call). With continueAfterCompact enabled (the default), the extension sends a follow-up
message once compaction finishes so the agent keeps working from where it left off.
The nudge is skipped if the context is still above the threshold after compaction, to avoid a compact → resume → compact loop.
Commands
/autocompact                            → show config + effective limit for current model
/autocompact set <percent>              → set the GLOBAL limit (compact when this % used)
/autocompact model <id> <percent>       → set a PER-MODEL limit (overrides global)
/autocompact unset <id>                 → remove a per-model override
/autocompact toggle                     → enable/disable auto-compaction
/autocompact continue [on|off]          → enable/disable resuming after compaction

# Quick one-command aliases (value = % of context USED at which to compact):
/set-auto-compact-limit 20                     → compact at 20% used (global)
/set-auto-compact-limit 10 model gpt-4o        → compact at 10% used for "gpt-4o"
Per-model limits always win over the global one. Use the provider/id or bare
id of the model, e.g. inferx/deepseek-v4-flash-0731, deepseek/deepseek-v4-pro,
or just gpt-4o. To make a model follow the global limit instead, remove its
override with /autocompact unset <id>.
All changes are saved to the config file and take effect immediately (no reload
needed); the footer status bar shows the active limit, e.g. auto-compact @20% used.
License
MIT