@thurstonsand/pi-librarian
Code research subagent for pi: deep-dive repos and discover across GitHub, GitLab, Bitbucket Server, and Sourcegraph; plus web search and URL-native fetch
Package details
Install @thurstonsand/pi-librarian from npm and Pi will load the resources declared by the package manifest.
$ pi install npm:@thurstonsand/pi-librarian- Package
@thurstonsand/pi-librarian- Version
0.9.1- Published
- Nov 6, 2026
- Downloads
- 1,321/mo · 609/wk
- Author
- thurstonsand
- License
- MIT
- Types
- extension
- Size
- 1.6 MB
- Dependencies
- 10 dependencies · 5 peers
Pi manifest JSON
{
  "extensions": [
    "./dist/pi/librarian.js"
  ]
}
Security note
Pi packages can execute code and influence agent behavior. Review the source before installing third-party packages.
README
pi-librarian
A code research subagent for the pi coding agent inspired by Amp: deep-dive questions about specific repos ("how does drizzle-orm implement prepared statements?") and discovery across the ecosystem ("compare the most popular TypeScript SQL ORMs"). It also gives your session, and every librarian run, web_search and web_fetch. Claude Code and Codex get the same librarian as a subagent.

How it works
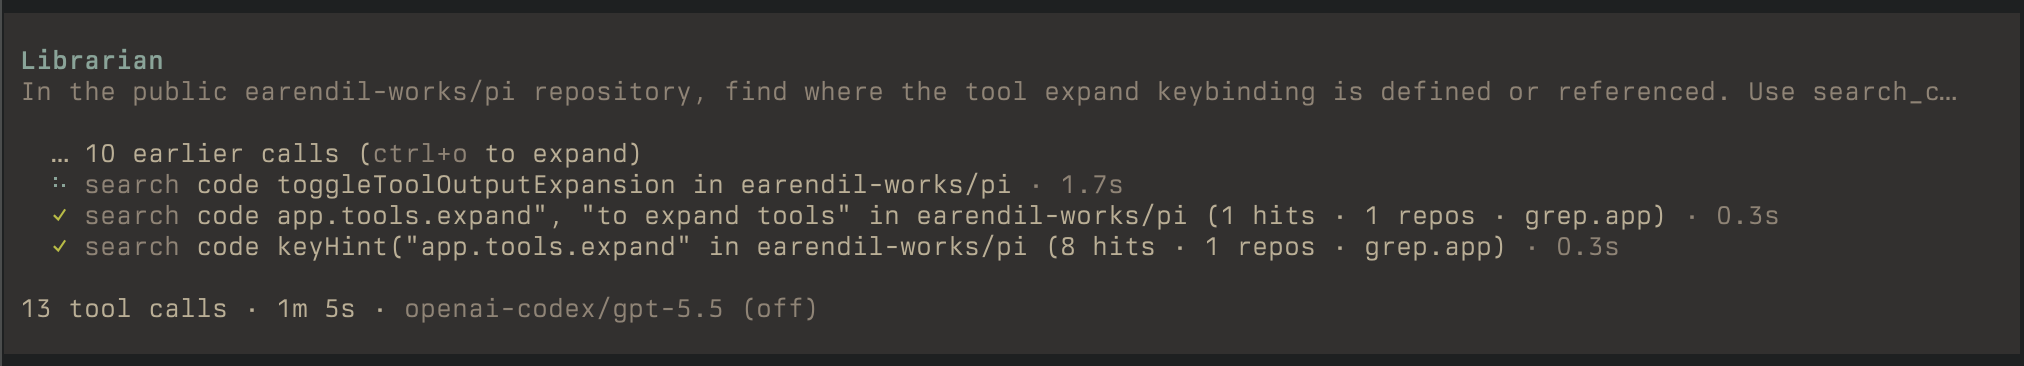
The librarian tool spawns a research subagent with purpose-built tools, built from the sources you configure. One tool per search engine, because every engine's query language and filters differ; a tool with no configured instance does not appear, and one with several takes a source argument naming which.
checkout_repo— clone into a local cache, where it can be read locally, andgit log -S/blame/diffcovers history. Takes a repository path plus asourcenaming one of your configured sources, or a full HTTPS/SSH clone URL on its own.read_file— read one file or list one directory from a code host without cloning.search_code_github— GitHub code search over public code and private repositories your token can read.search_code_grepapp— public code search via Grep, with regex.search_repos_github— GitHub repository discovery by name, topics, language, stars, and activity.search_code_gitlab,search_repos_gitlab— with a declared GitLab: exact-string code search within a project (across projects withadvancedSearch), held to GitLab's 30 code searches a minute, and project search by name, group, topic, and activity.search_code_bitbucket,search_repos_bitbucket— with a declared Bitbucket Server: whole-word code search across every repository, and repository search by the start of a name.search_code_sourcegraph,search_repos_sourcegraph,find_definition— with a declared Sourcegraph: code search across every repository it indexes, with adetailof repos, files, or matched lines and a statement of whether it covered them all; repository search by name, topic, contained path, or recent commits; and symbol definitions by exact name, leaving vendored copies out unless asked.web_search,web_fetch— the web tools, which librarian runs get as well.
Every search returns a short digest, 10 results unless the librarian asks for up to 50 (grep.app returns 10 at most), and writes the full result set to a file it can grep. A search that runs past its 15-second budget is an error that says how to narrow it, never a partial answer.
Usage
- Ask pi a question involving other repos; it asks the
librarian. - Ask follow-up questions to earlier librarian runs.
/librarianattaches the research tools directly to your session for direct tool usage.web_searchandweb_fetchare always in your session;/browser openopens the fetch browser so you can log in to sites it should reach.
Claude Code and Codex
Both get a librarian subagent that runs the same research tools as a librarian command, so the tools stay out of the main agent's context. The command lists only the sources you configured; librarian --help and each command's --help document the rest. Clones, results, the browser profile, and the fetch worker are shared with pi. Each plugin runs the command through npx, pinned to its own version, when librarian is not on PATH.
Claude Code
/plugin install librarian --marketplace thurstonsand/pi-librarianFrom a shell, claude plugin install librarian --marketplace thurstonsand/pi-librarian does the same.
The subagent runs on Sonnet. To change it, set CLAUDE_CODE_SUBAGENT_MODEL together with CLAUDE_CODE_SUBAGENT_MODEL_FORCE=1, which applies to every subagent. The plugin's hooks let only the librarian subagent run librarian and read and search its cache without a permission prompt. Claude Code's sandbox is not supported; to use one, allow Bash(librarian *) in your own settings.
Codex
codex plugin marketplace add thurstonsand/pi-librarian
codex plugin add librarian@pi-librarian
Codex plugins cannot ship agents, so the plugin ships a librarian skill that tells the main agent to spawn a subagent and hand it the librarian's prompt. Under auto review or full access that is all it needs. Codex's default sandbox blocks the librarian's network and asks for every clone and fetch, and codex exec cannot ask at all; for those, install the command and give Codex a real librarian role and a rule that runs it outside the sandbox:
npm install --global @thurstonsand/pi-librarian
librarian codex setup
codex setup writes ~/.codex/agents/librarian.toml, with the model and reasoning effort from the codex settings, and ~/.codex/rules/librarian.rules, reporting each as created, updated, or unchanged; restart Codex after it changes either. The skill prefers that role when it exists. Rerun codex setup after upgrading or after changing the codex settings. librarian codex uninstall asks once, then removes both files.
Web tools
This package absorbed pi-web-tools, which is deprecated. Uninstall it: both register web_search and web_fetch, and pi reports the clash at startup.
web_search
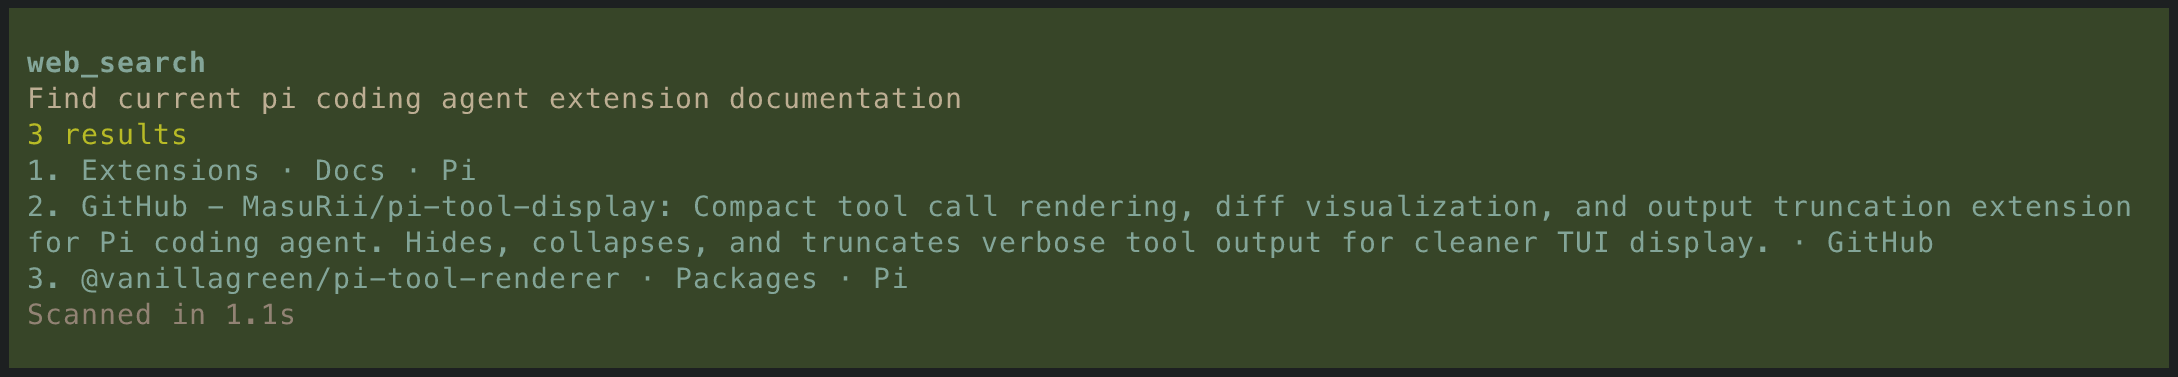
Backed by Parallel, and registered only when a Parallel key is configured. It takes an objective and returns results with excerpts.
Parameters:
objective(required) — what you want to learn.search_queries— up to 8 specific queries.max_results— 1–8, defaults to 5.after_date—YYYY-MM-DDfreshness filter.
web_fetch
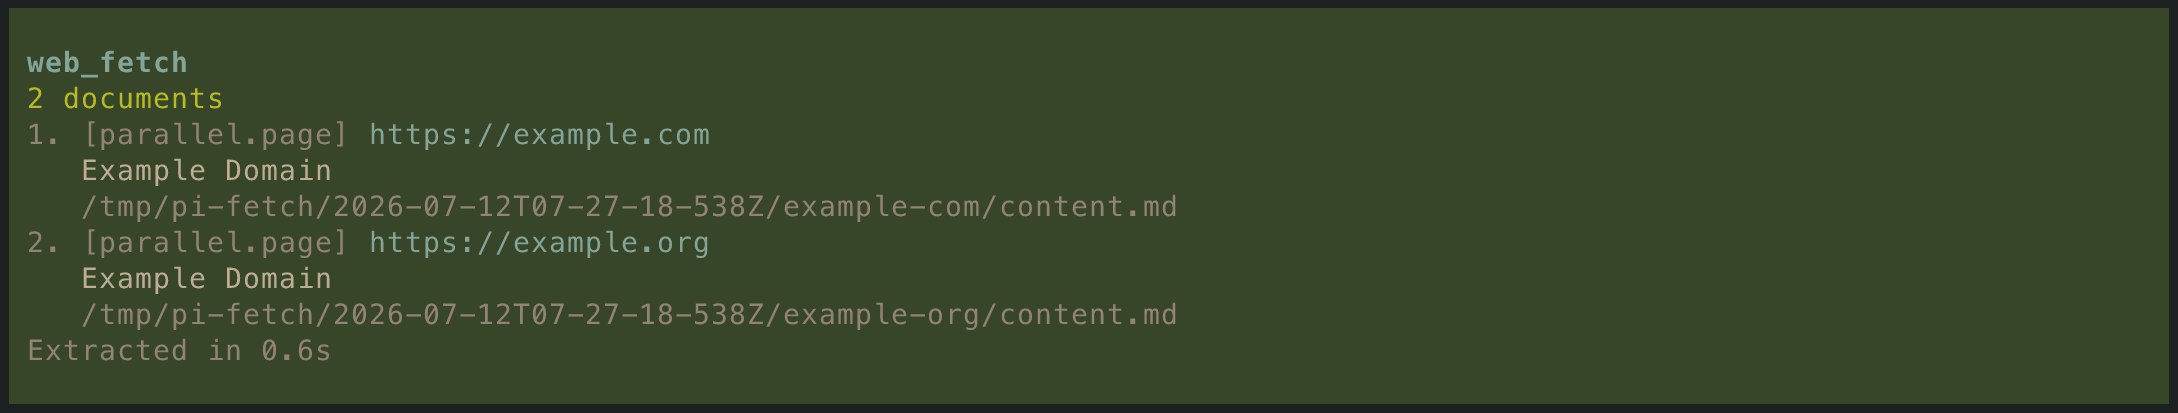
Fetch up to 10 URLs at once. Each document's body is written under <cacheDir>/fetches/<call>/ as a native artifact (markdown, patch, source file), and the tool result is a digest: title, facts, the artifact paths with sizes, and a capped excerpt. Pass an optional objective to steer extraction where supported.
Each URL goes through a chain of fetchers, github → parallel → local; the first to produce a document wins.
GitHub resolves URLs on github.com and on any github source you declare, through the same client and token as the repo tools:
- Repository READMEs, files (including
blobandrawURLs), and directories as a listing - Issues, pull requests, and Discussions with their conversations; PRs also carry the diff. An issue carries its timeline filtered to closes, reopens, and references, and says when a commit closed it, because closed as
completedalone can mean the reporter was answered rather than the bug fixed. - Issue and PR listings,
github.com/{owner}/{repo}/issuesor/pulls, optionally with?q=in GitHub search syntax, up to 100 matches, each with its state and reason - Commits with metadata, comments, and a patch; commit history, optionally scoped by ref and path, up to 100 commits
- Releases (tagged, latest, and listings), tags, and branches
- GitHub Actions runs with jobs, steps, and artifact metadata
Parallel extracts anything else, when a key is configured.
Local is a browser fallback: playwright-core driving a Chromium browser, with a rehype HTML-to-markdown pipeline. It uses executablePath when set, then Google Chrome, then a chromium on PATH, then Playwright's own Chromium, which the first local fetch downloads when nothing else exists and says so in its result. One worker and one browser serve every pi, Claude Code, and Codex session. It reaches pages behind a login once you have logged in through /browser open, and downloads non-HTML files such as PDFs. A bot-wall challenge that does not clear headless within headlessWaitSecs briefly opens a visible window for up to headedWaitSecs, unless escalation is "never". /browser restart applies changed browser settings.
GitHub auth for private repos
Public GitHub reads work without configuration. To let the librarian search and read private GitHub repositories, provide a token in one of these ways:
- Set
GITHUB_TOKENorGH_TOKENin the environment before starting pi. - Or authenticate the GitHub CLI so
gh auth tokenreturns a token:
The token is loaded once per session and used for GitHub access in search_code_github, search_repos_github, read_file, and web_fetch. For private repositories, use a token with read access to the target repos. checkout_repo uses git's built-in credential helpers instead.
Configuration
In ~/.config/agents/librarian/config.json, under $XDG_CONFIG_HOME when set, shared by every harness:
{
  "sources": [
    {
      "name": "example-gl",
      "url": "https://gitlab.example.com",
      "kind": "gitlab",
      "tokenEnv": "EXAMPLE_GITLAB_TOKEN",
      "advancedSearch": false,
      "description": "Holds the services not yet migrated to example-bb."
    },
    {
      "name": "example-bb",
      "url": "https://git.example.com",
      "kind": "bitbucket-server",
      "disabled": ["code-search"]
    },
    {
      "name": "example-sg",
      "url": "https://search.example.com",
      "kind": "sourcegraph",
      "tokenCommand": "op read op://Private/Sourcegraph/credential"
    }
  ],
  "builtInSources": { "github": true, "gitlab.com": false },
  "search": { "timeoutSeconds": 15, "defaultLimit": 10 },
  "web": {
    "parallel": { "apiKeyCommand": "op read op://Private/Parallel/credential" },
    "fetch": {
      "browser": {
        "executablePath": "/Applications/Google Chrome.app/Contents/MacOS/Google Chrome"
      },
      "challenge": { "escalation": "headed", "headlessWaitSecs": 10, "headedWaitSecs": 20 }
    }
  },
  "cacheDir": "~/.cache/agents/librarian",
  "pi": {
    "model": "openai-codex/gpt-5.5",
    "thinkingLevel": "off",
    "tools": { "disabled": [] },
    "debug": { "persistRuns": false }
  },
  "codex": { "model": "gpt-5.5", "reasoningEffort": "low" }
}
Earlier releases kept these settings under librarian in pi's settings.json, and the browser profile at ~/.pi/agent/browser-profile. The first pi, Claude Code, or Codex session after upgrading moves both, filing model, thinkingLevel, tools, and debug under pi. When the new location already exists it stops with an error instead of choosing one.
| Setting | Recommended | Default |
|---|---|---|
sources |
code hosts and search backends | [] |
builtInSources |
switch github and gitlab.com on or off |
github on, gitlab.com off |
search.timeoutSeconds |
seconds a search may run before it is an error | 15 |
search.defaultLimit |
results a search returns unless asked for more (at most 50) | 10 |
web.parallel.apiKeyCommand |
shell command printing a Parallel key, run per call | PARALLEL_API_KEY only |
web.fetch.browser.executablePath |
the browser the local fetcher drives | Chrome, then a chromium |
web.fetch.browser.profileDir |
the fetch browser's profile | ~/.local/state/agents/librarian/browser-profile |
web.fetch.challenge.* |
escalation (headed or never), headlessWaitSecs, headedWaitSecs |
headed, 10, 20 |
cacheDir |
clones, search results, and fetched pages | ~/.cache/agents/librarian |
pi.model |
openai-codex/gpt-5.5 |
current session model |
pi.thinkingLevel |
off |
current session thinking level |
pi.tools.disabled |
names of tools to remove from librarian runs | [] |
pi.debug.persistRuns |
persist nested session file paths for debugging | false |
codex.model, codex.reasoningEffort |
the Codex role's model and reasoning effort, applied by codex setup |
the parent session's |
Each sources entry requires a unique name, an HTTPS url, and a kind: github, gitlab, bitbucket-server, or sourcegraph. The kind decides which roles a source can play — clone, code-search, repo-search — unless disabled. github and gitlab.com are built in and need no entry; builtInSources switches each on or off as a whole, and a switched-off source does not exist at all, though a full clone URL to its host still clones.
Search needs an API token; cloning does not, because it uses git's own credentials. A source reads its token from the environment variable named by tokenEnv, from what tokenCommand prints, or by default from its kind's usual variable: GITHUB_TOKEN/GH_TOKEN, GITLAB_ACCESS_TOKEN, BITBUCKET_TOKEN, SRC_ACCESS_TOKEN. tokenCommand runs once, the first time the source is used, and outside the search time limit; restart the session after rotating the token it prints. A source without a token keeps cloning and loses its search tools. advancedSearch: true, on a gitlab source only, says the instance has GitLab's advanced search, which lets code search span projects. description is up to 300 characters the agent cannot discover for itself, such as what a Sourcegraph does not index; it ends the description of every tool that reaches that source, so attached tools carry it too. Note that pi.tools.disabled is a different lever: it removes a tool from the run entirely, where a source's disabled removes one source from one role.
Every key in the file is checked, and an unknown one is an error rather than ignored. Pi's librarian runs have read, grep, find, ls, bash, the research tools, and the web tools; never write or edit.
Development
npm run check                       # biome + tsc + vitest + build
pi -e ./src/pi/librarian.ts         # run pi with this extension loaded
mise run build && node dist/cli/librarian.js --help   # build and run the CLI