pi-llama-infra
Discovery, metrics and control of llama.cpp-family servers and OpenAI-compatible servers for pi (llama.cpp, ZINC, DwarfStar/ds4, lucebox, LM Studio, vLLM, SGLang, TGI, halogen): scan machines (localhost, LAN, Tailscale), register models, read real context
Package details
Install pi-llama-infra from npm and Pi will load the resources declared by the package manifest.
$ pi install npm:pi-llama-infra- Package
pi-llama-infra- Version
1.4.3- Published
- Sep 15, 2026
- Downloads
- 253/mo · 253/wk
- Author
- noguerol
- License
- MIT
- Types
- extension
- Size
- 199.4 KB
- Dependencies
- 0 dependencies · 2 peers
Pi manifest JSON
{
  "image": "https://raw.githubusercontent.com/noguerol/llama-infra/main/docs/preview.jpeg",
  "extensions": [
    "./src/index.ts"
  ]
}
Security note
Pi packages can execute code and influence agent behavior. Review the source before installing third-party packages.
README
llama-infra — Discovery, Metrics & Control for Local LLM Runtimes
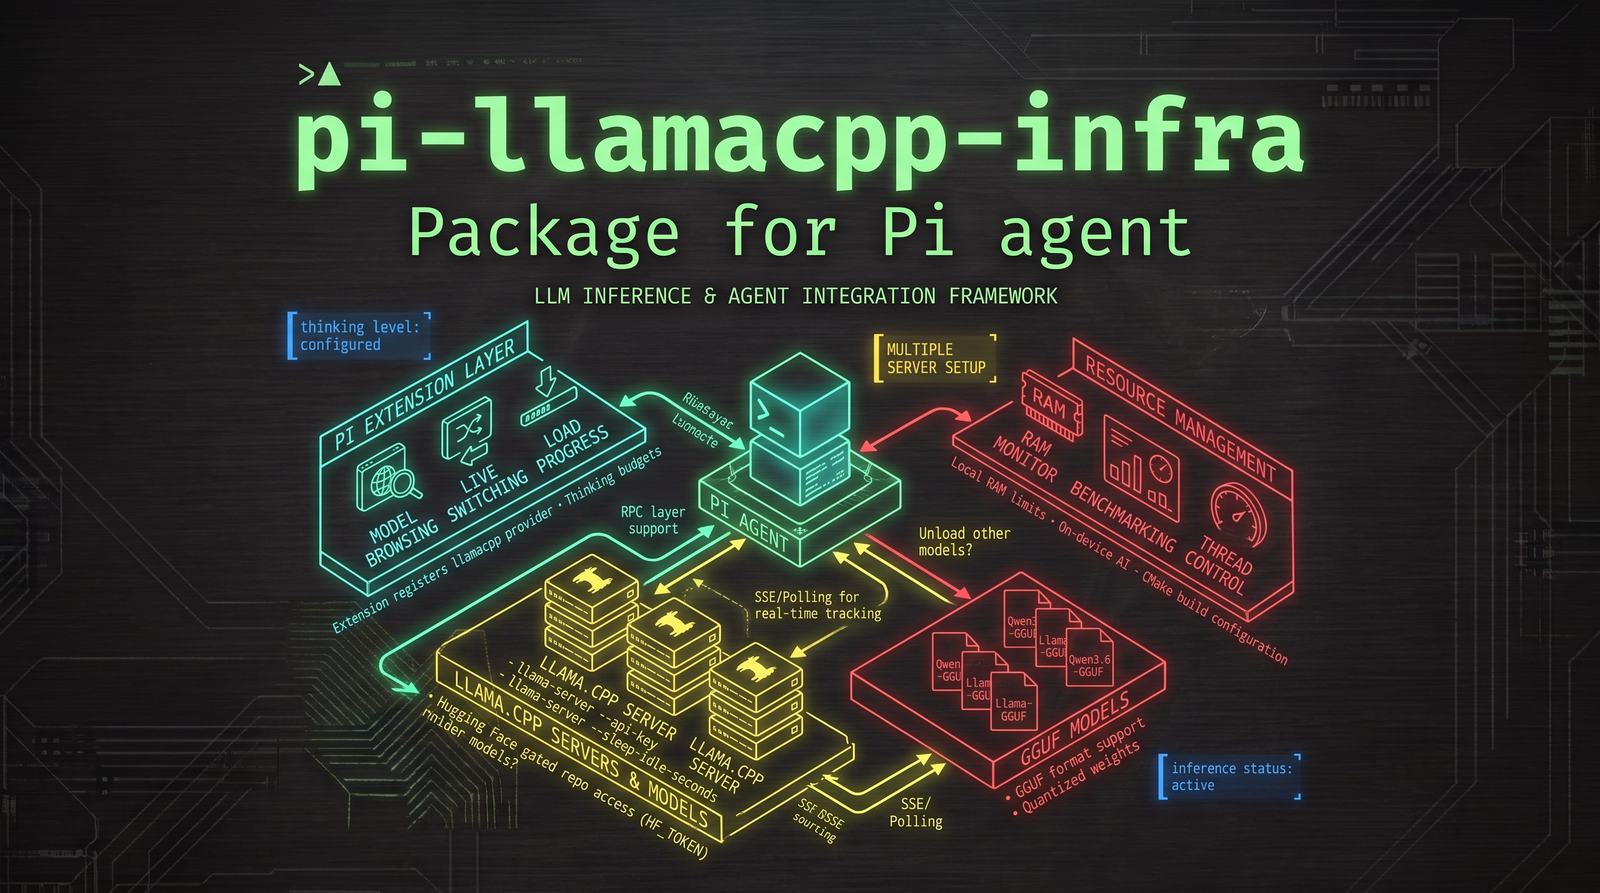
llama-infra turns pi into a first-class citizen of your local LLM infrastructure. It is built primarily around llama.cpp and its family (ZINC, DwarfStar/ds4, lucebox, LM Studio), and now also speaks the most popular OpenAI-compatible runtimes — vLLM / SGLang / TGI — and the halogen engine. It probes any number of machines — localhost, LAN or Tailscale — discovers every served model, registers them into pi's native /model list, and gives you live Prometheus metrics, per-model thinking budgets, vision detection and a full configuration UI — all without leaving the pi prompt.
Supported Servers
Every endpoint llama-infra talks to runs llama.cpp, a direct variant, or an OpenAI-compatible server (vLLM-family or halogen):
| Server | Detection | Notes |
|---|---|---|
| llama.cpp | GET /v1/models with meta.n_ctx |
Single-model and router/multi-model modes |
| ZINC | owned_by: "zinc" |
Payload workaround: empty model field + tool normalization |
| DwarfStar / ds4 | Opt-in ping to /v1/chat/completions |
antirez's ds4-server for DeepSeek V4 (per-server probeDs4 flag) |
| lucebox | GET /props with server.name: "luce-*" |
DeepSeek dflash server with rich metadata |
| LM Studio | GET /v1/models + optional /api/v1/models metadata |
Local OpenAI-compatible server backed by llama.cpp; default port 1234 |
| vLLM / SGLang / TGI | owned_by: "vllm" in GET /v1/models |
OpenAI-compatible runners; context from max_model_len; no /props, no /slots; thinking via thinking_token_budget |
| halogen | owned_by: "halogen" in GET /v1/models with no /props |
OpenAI-compatible engine; context read from GET /health (slot_ctx / context); metrics served in the llamacpp: namespace (see halogen) |
Anything else (Ollama, cloud APIs…) is out of scope — use pi's built-in providers for those.
Features
- Multi-machine discovery — configurable list of servers (host, ports, API key, options); probes all of them at startup and on demand
- Compact model ids — models appear as
Name (host:port)in pi's/modelpicker, like a native provider; the raw GGUF path/alias is sent to the server automatically on every request - Single-model & router modes — llama.cpp single-model mode (one GGUF per instance) and router mode (multiple models per server, with per-model status and args)
- Long local generations — discovered models are registered with up to 32,768 output tokens (bounded by the model/server context) and llama-infra OpenAI-compatible requests enforce a 20 minute timeout floor so slow local runs don't get cut early by pi defaults
- Per-model metadata badges — 👁️ vision (mmproj / modalities), 🚀 drafter (speculative decoding), 🗜️ quant tag from GGUF filename, 🧠 KV cache quantization (from server args or
/proc) - Live speed & metrics — a constantly updating footer reading of the active model's prefill (⚡) and generation (🔥) token speed, measured straight from the stream (per token, ~10 updates/s); when pi is idle it also mirrors other clients the server's
/metricsendpoint reports. Lives in the footer's status line, so no extra terminal row is taken. Works even without--metrics - Energy cost (💰) — local models report no per-token cost, so llama-infra estimates the electricity the inference consumed: configure each machine's power draw (kW) and tariff (per kWh) once, and every assistant message carries a realistic
usage.cost.total(kW × €/kWh × measured request time) — pi's native cost footer, session stats and any consumer reading usage (e.g. trimegisto agents) all show it. Currency selector: USD / EUR / GBP / CNY - Thinking budgets — llama.cpp accepts
thinking_budget_tokensper request; configure budgets per thinking level (minimal/low/medium/high/xhigh/max) per model; models with budgets are registered with reasoning enabled - Header warmup — pre-caches the system prompt KV on llama.cpp-family servers so the first real request is faster
- LM Studio support — uses LM Studio's OpenAI-compatible
/v1API, enriches names/context/quant/vision from/api/v1/models(or legacy/api/v0/models), and avoids llama.cpp-only request fields - vLLM / SGLang / TGI support — auto-detects
owned_by: "vllm", reads the context window frommax_model_len, normalizes thevllm:metrics namespace, and uses vLLM's ownthinking_token_budgetfield (see vLLM / SGLang / TGI) - halogen support — auto-detects
owned_by: "halogen"and pulls the real context window from/health(slot_ctx/context), with an 8 s probe floor and a sticky per-machine value, so pi never compacts at the 32k fallback on a 262k model (see halogen) - ZINC workaround — ZINC rejects non-empty model IDs; the payload hook rewrites the request and normalizes tool definitions automatically
- Vision detection — scans
/procfor local llama-server processes launched with--mmprojand marks those models as image-capable; also reads server-reportedmodalities/input_modalities - Native configuration UI — everything configurable through
/llama-infra configwith pi's native menus; no config file editing required - Legacy migration — auto-migrates an existing
~/.pi/agent/local-models.jsonon first run
Install
llama-infra is a pi package: a small entrypoint (src/index.ts) backed by several focused modules. Heavier pieces (UI, scan engine, metrics, header warmup) are loaded lazily on first use so the extension stays light at startup. The package is declared in package.json.
# From GitHub
pi install git:github.com/noguerol/llama-infra

# Pin a tag/commit
pi install git:github.com/noguerol/llama-infra@v1.2.0

# From npm
pi install npm:pi-llama-infra

# Local checkout (development)
pi install /path/to/llama-infra

# Try it for one run only
pi -e git:github.com/noguerol/llama-infra
pi list                         # show installed packages
pi remove npm:pi-llama-infra
Security: pi packages run with full system access. Install only packages you trust and review the source.
Requirements: a working pi installation and at least one supported server running somewhere accessible (localhost, LAN or Tailscale): a llama.cpp-family server, an OpenAI-compatible vLLM/SGLang/TGI endpoint, or a halogen server. LM Studio works when its local server is started (Developer tab or lms server start, usually on http://localhost:1234/v1).
Quick Start
/llama-infra config      # open the config menu → add your first server (LM Studio: port 1234)
/llama-infra scan        # discover models now
/llama-infra list        # see what was found
That's it. On the next pi startup, llama-infra probes your servers automatically and registers every model into /model. Switch models with /model as usual.
LM Studio quick setup
LM Studio exposes an OpenAI-compatible API on /v1 (default http://localhost:1234/v1) and a richer local REST API for model metadata on /api/v1/models (older LM Studio versions used /api/v0/models). llama-infra probes /v1/models as the source of usable model IDs and, when available, enriches them with LM Studio's context length, display name, quantization and vision capability.
# Start LM Studio's local server (or use the Developer tab in the GUI)
lms server start

# In pi: add/select host 127.0.0.1 with port 1234, then scan
/llama-infra config
/llama-infra scan
No special payload workaround is required: LM Studio accepts standard OpenAI chat-completions requests. llama-infra deliberately does not send llama.cpp-only fields such as cache_prompt or thinking_budget_tokens to LM Studio.
vLLM / SGLang / TGI
OpenAI-compatible servers that advertise owned_by: "vllm" in GET /v1/models are detected automatically — no extra flags. vLLM/ROCm is the reference case (ciru-halo-agent on 127.0.0.1:8081); SGLang/TGI reuse the same code path.
Discovery & context — the server kind comes from owned_by: "vllm" and the context window from max_model_len (e.g. 262144 for ciru-halo-agent). vLLM has no /props and no /slots, so llama-infra skips both probes entirely (llama.cpp still uses them). The built-in default servers already probe port 8081:
curl -s http://127.0.0.1:8081/v1/models | jq -r '.data[0] | "\(.id) owned_by=\(.owned_by) ctx=\(.max_model_len)"'
# ciru-halo-agent owned_by=vllm ctx=262144
Thinking budgets — vLLM's Qwen chat template exposes chat_template_kwargs.enable_thinking (verified: false → 0 reasoning tokens, true → reasoning is produced). The budget field is vLLM's own thinking_token_budget — not llama.cpp's thinking_budget_tokens — and it caps reasoning tokens while thinking is on (verified: 64 → 63, 128 → 127; 512 had no effect because the model stopped on its own). Configure per-level budgets under modelOptions as usual; for vLLM models the extension injects thinking_token_budget. preserve_thinking, reasoning_budget_tokens and chat_template_kwargs.reasoning_effort are accepted but ignored by this server.
Metrics — Prometheus names are normalized from the vllm: namespace (just like llamacpp:), so the footer ⚡/🔥 and ▶n (other clients) readings work unchanged. Generation rate is read from vllm:generation_tokens_total.
Manual overrides — vLLM publishes neither vision modality nor drafter/spec-decode info, and the local process scanner only recognizes llama-server. Set them explicitly per model:
{ "modelOptions": { "ciru-halo-agent": { "vision": false, "drafter": "DFlash2 15/7" } } }
Known limitations
- Vision is never auto-detected — force it with
modelOptions[id].vision = true. - Drafter/spec-decode gets no name badge unless set via
modelOptions[id].drafter; when vLLM exposesvllm:spec_decode_*, the footer shows the drafter acceptance ratio (🎯). cacheK/cacheVKV-quant badges stay empty (GGUF/llama.cpp-specific).- No
/slots, so server-side idle stats come fromvllm:num_requests_running, plus the spec-decode acceptance ratio (🎯) and prefix-cache hit ratio (♻️) derived from thevllm:counters. - vLLM serves one model per process; the server
modestayssingle. - The server enforces a hard limit and returns HTTP 400 when prompt +
max_tokensexceedsmax_model_len; a correctcontextWindowkeeps pi's compaction predictable. - This particular server does not validate types (e.g.
enable_thinking: "false"is accepted); pi always sends proper booleans.
Ready-to-paste ~/.pi/agent/llama-infra.json
{
  "servers": [
    { "id": "local", "host": "127.0.0.1", "label": "Local",
      "ports": [8080, 8081, 8082], "enabled": true,
      "costProfile": { "kW": 0.095, "ratePerKwh": 0.15 } },
    { "id": "strix", "host": "bruma", "label": "bruma (Strix Halo)",
      "ports": [8081], "enabled": true }
  ],
  "settings": {
    "discoveryTimeoutMs": 2000,
    "prefixModelIds": true,
    "showBadgesInNames": true,
    "detectVision": true,
    "metricsEnabled": true,
    "maxOutputTokens": 32768
  },
  "modelOptions": {
    "ciru-halo-agent": { "vision": false }
  }
}
Per-level thinking budget for the registered vLLM model (injected as thinking_token_budget):
{
  "modelOptions": {
    "Ornith1.5-Ciru-Halo-Agent (127.0.0.1:8081)": {
      "thinkingBudgets": { "minimal": 256, "low": 1024, "medium": 4096, "high": 16384 }
    }
  }
}
halogen
halogen is a proprietary OpenAI-compatible engine. It answers GET /v1/models like everyone else, but publishes neither /props nor meta.n_ctx — the context window lives only in GET /health. Without reading it, the registration chain falls back to 32,768 and pi compacts at ~33k on a model serving 262,144.
Detection — a model with owned_by: "halogen", no /props answer, and a reachable /health is picked up automatically, with no extra flags. halogen servers are registered into the llama.cpp family:
curl -s http://127.0.0.1:8081/v1/models | jq -r '.data[0] | "\(.id) owned_by=\(.owned_by)"'
# halogen-qwen3.8-flash-next owned_by=halogen

curl -s http://127.0.0.1:8081/health | jq '{context, slot_ctx, slots}'
# { "context": 262144, "slot_ctx": 262144, "slots": 3 }
Context grafting — once per scan, llama-infra probes /health at the server root and grafts slot_ctx (preferred) or context onto every model as meta.n_ctx and max_model_len, never overwriting a value the server did publish.
Slow-health guard (8 s floor) — /health pings the engine itself (engine.probe_s), so it can take seconds while a request is in flight or under memory pressure. The generic discoveryTimeoutMs (2 s by default) is too short for that: the health probe gets a floor of 8 s regardless, so a busy engine never looks like a missing one.
Sticky context — the last good context is remembered per host:port. If a later scan's /health probe stalls, llama-infra reuses the remembered value instead of regressing to the 32,768 fallback, so the registered contextWindow stays stable and pi's compaction stays predictable across scans.
What works out of the box — halogen models are registered as llama.cpp-family:
| Area | Behaviour |
|---|---|
| Context window | the real served context from /health (e.g. 262,144), not the fallback |
| Compaction | driven by that real context |
| Metrics | /metrics is served in the llamacpp: namespace → footer ⚡ prefill / 🔥 generation work unchanged |
| Long generations | 32k output cap and the 20 minute timeout floor, same as llama.cpp |
| Thinking budgets | injected under llama.cpp's field name thinking_budget_tokens (the family default) |
Thinking budgets on halogen — the engine publishes its own knobs as
reasoning_effortandmax_thinking_tokens, and its/healthsupportedlist is the authority on what a request may set. Whether it also maps llama.cpp'sthinking_budget_tokensis unverified: treat per-level budgets on halogen as best-effort and check/healthbefore relying on them.
Manual overrides — halogen reports vision.enabled, drafters_available and drafter_default in /health, but llama-infra reads only the context from it today. Set the rest per model:
{ "modelOptions": { "halogen-qwen3.8-flash-next": { "vision": true, "drafter": "mtp" } } }
Known limitations
- Vision is not auto-detected — force
modelOptions[id].vision = true(the server's own/healthreportsvision.enabled). - The 🚀 drafter badge stays empty unless set via
modelOptions[id].drafter. - A halogen server that has never answered
/healthregisters with the 32,768 fallback until the first successful probe (then the value sticks). - halogen takes images as
data:URLs or bare base64 and refuseshttp(s)image URLs — a server-side contract, not a llama-infra setting.
Commands
| Command | Description |
|---|---|
/llama-infra |
Quick status (servers, discovered models, metrics) |
/llama-infra config |
⚙️ Interactive configuration menu |
/llama-infra scan |
Rescan all servers now |
/llama-infra status |
Detailed per-endpoint report |
/llama-infra list |
List discovered models with metadata badges |
/llama-infra metrics |
Toggle live speed & metrics in the footer |
/llama-infra help |
Command help |
/llama-infra config
The main config menu branches into submenus:
- 🖥️ Servers — add/remove/edit servers; per-server settings (host, ports, API key, probeDs4, label)
- 🔄 Scan — rescan all servers now
- 📋 Models — per-model options (thinking budgets, replace/remove)
- 🧪 Test — connectivity test of all configured servers
- 🧠 Thinking budgets — configure per-model thinking_budget_tokens per level
- 📈 Metrics — enable/disable footer metrics, server poll interval
- ⚙️ Settings — discovery timeout, poll interval/budget, startup grace, fail limit, vision detection, prefix model IDs, name badges, unloaded router models, header warmup
- ℹ️ About — extension info
/llama-infra list
Shows every discovered model with metadata badges:
📋 Discovered models (8)

 1. Qwen3.6-27B-UD-Q3_K_XL (local:8080)   👁️ 🗜️ UD-Q3_K_XL
 2. DeepSeek-V4-Flash-ROCMFP2 (local:8081)          🗜️ ROCMFP2
 3. Meta-Llama-3.1-8B (myserver:8080)     🚀 draft-model   🗜️ Q4_K_M
 4. gemma-3-4b-it (myserver:8081)         👁️ 🗜️ Q4_K_M
The same compact id is what pi's /model picker shows, with the serving machine in parentheses.
/llama-infra status
Detailed per-endpoint report:
🖥️ Server status

 local (127.0.0.1)
   :8080  ✅ llama.cpp  b3421  2 models  👁️ vision
   :8081  ✅ lucebox    dflash 1 model

 myserver (192.168.1.20)
   :8080  ✅ llama.cpp  b3421  1 model   🚀 drafter
   :8081  ❌ timeout
Configuration
Everything is configurable through the UI, but the persisted file is ~/.pi/agent/llama-infra.json:
{
  "servers": [
    {
      "id": "local",
      "host": "127.0.0.1",
      "label": "Local",
      "ports": [8000, 8001, 8002, 8080, 8081, 8082, 1234],
      "enabled": true,
      "probeDs4": false,
      "costProfile": { "kW": 0.15, "ratePerKwh": 0.21, "label": "bruma 27B" }
    },
    {
      "id": "myserver",
      "host": "myserver",
      "label": "My Server",
      "ports": [8080, 8081],
      "enabled": true,
      "probeDs4": true,
      "apiKey": "optional-bearer-token"
    }
  ],
  "settings": {
    "discoveryTimeoutMs": 2000,
    "pollIntervalMs": 4000,
    "pollMaxMs": 90000,
    "startupGraceMs": 40000,
    "knownGoodFailLimit": 3,
    "detectVision": true,
    "prefixModelIds": true,
    "showBadgesInNames": true,
    "includeUnloadedRouterModels": false,
    "warmup": true,
    "metricsEnabled": true,
    "metricsPollMs": 5000,
    "currency": "eur",
    "costTracking": true
  },
  "modelOptions": {
    "Qwen3.6-27B (myserver:8080)": {
      "thinkingBudgets": {
        "minimal": 256,
        "low": 1024,
        "medium": 4096,
        "high": 16384
      }
    }
  }
}
Server fields
| Field | Default | Description |
|---|---|---|
id |
required | Unique short id (used in model IDs and logs) |
host |
required | Hostname, tailnet name or IP |
label |
host |
Friendly name shown in menus |
ports |
required | Array of ports to probe (1234 is LM Studio's usual local server port) |
enabled |
true |
Whether to probe this server |
probeDs4 |
false |
Opt-in: ping /v1/chat/completions for DwarfStar/ds4 servers |
apiKey |
— | Optional bearer token sent on discovery and per-model requests |
costProfile |
— | { kW, ratePerKwh } energy-cost profile for this machine; enables 💰 estimation (see Energy Cost) |
Settings
| Setting | Default | Description |
|---|---|---|
discoveryTimeoutMs |
2000 |
Per-request timeout when probing endpoints |
pollIntervalMs |
4000 |
Background re-poll rate while servers load models |
pollMaxMs |
90000 |
Max total polling time |
startupGraceMs |
40000 |
Keep trying at startup while nothing has answered |
knownGoodFailLimit |
3 |
Consecutive failures before a live endpoint is dropped |
detectVision |
true |
Scan /proc for --mmproj + read server-reported modalities |
prefixModelIds |
true |
Append the machine tag (host:port) to model ids; OFF keeps bare names and only disambiguates collisions |
showBadgesInNames |
true |
Append 👁️🚀💤 badges to model display names |
includeUnloadedRouterModels |
false |
Router mode: list models that are not currently loaded |
| output cap | 32768 |
Registered per model as maxTokens unless the server reports an explicit max_tokens; still bounded by available context |
| request timeout | 1200000 |
20 minute timeout floor applied to llama-infra OpenAI-compatible streams |
warmup |
true |
Pre-cache system prompt KV on llama.cpp servers |
metricsEnabled |
true |
Show live speed & metrics in the footer for llama-infra models |
metricsPollMs |
5000 |
How often /metrics is fetched |
currency |
eur |
Display currency for energy costs: usd / eur / gbp / cny |
costTracking |
true |
Accumulate 💰 energy cost and inject it into usage.cost.total |
Thinking budgets
llama.cpp accepts thinking_budget_tokens per request; vLLM instead accepts thinking_token_budget (the extension picks the right field per server kind). Configure budgets per thinking level per model through the config menu (🧠 Thinking budgets → select model → set level). Models with any budget configured are registered with reasoning: true, and pi sends the budget automatically when the thinking level matches.
Levels: minimal, low, medium, high, xhigh, max.
Model ID Format
Models are registered with compact display ids: ModelName (host:port), e.g. Qwen3.6-27B-UD-Q3_K_XL (myserver:8080) — the compact model name plus the machine serving it in parentheses, matching how pi shows native provider models. Localhost servers (127.0.0.1, localhost) use local:port in the tag.
pi sends the compact id to the extension's request hook, which transparently rewrites it to the raw server-side id (the GGUF path, alias or router id the server advertised in /v1/models) before the request leaves pi. Config keys under modelOptions use the compact id; legacy host:port/model keys are migrated automatically on the first scan.
With prefixModelIds: false the machine tag is omitted (ModelName); it is re-added automatically only when two models would otherwise collide.
Thinking budgets in the UI
llama.cpp-family models are registered as reasoning models, exactly like a native pi provider: the footer shows ModelName (host:port) • <level>, the thinking selector offers levels with token estimates, and pi sends the configured thinking_budget_tokens budget on each request. Per-model budgets configured in the extension override pi's global per-level budgets.
Live Speed & Metrics (footer)
When enabled, the speed reading appears in the footer's status line (no extra terminal row) whenever the active model is from llama-infra, updating constantly while tokens flow. Both entries are kept ultra-compact so they coexist with other extensions on pi's single status line (which truncates from the end):
🦙(12) ⚡…            (before the first token)
🦙(12) ⚡ 420 t/s 🔥 38.1 t/s  (while streaming)
🦙(12) ⚡ 420 t/s 🔥 38.1 t/s  (just after the answer ends)
🦙(12) ⏸             (between turns)
🦙(12) ▶2 ⚡ 150 t/s 🔥 18.0 t/s  (pi idle, server busy for other clients)
🦙(12) ⏸ 💰3.2c      (energy cost of this session, after a turn)
(🦙(n) is the extension's model-count status; both live on the same footer line, so no extra row is consumed.)
- Client measurement (always, no
--metricsneeded) — prefill speed =prompt tokens ÷ (request → first token)(pi'susage.input, OpenAI-styleprompt_tokensas fallback); generation speed = a moving 1.5 s window over per-token arrival samples. Updated ~every 100 ms while a stream is live (throttled, and unchanged text is skipped, so the footer never churns). - Server supplement (only when pi is idle) — the poller fetches the server's Prometheus
/metricsendpoint (or JSON/stats) everymetricsPollMs(default 5 s). If the server reports other clients processing, their ⚡/🔥 rates are shown (▶n); when the server is idle, the plain⏸reading returns.
Energy Cost (💰)
Cloud providers report their own per-message cost, so pi's native cost footer is always right for them. Local llama.cpp-family servers report nothing — so llama-infra estimates the electricity the inference consumed and feeds it into the standard usage pipeline:
cost = (requestMs / 3_600_000) × kW × tariff
Every assistant message therefore carries a realistic usage.cost.total: pi's own cost display/session stats show it, and any consumer that reads usage (e.g. trimegisto sub-agents, which accumulate usage.cost.total per message into their dashboard) gets it for free — no per-tool cost logic needed anywhere else.
Setup
/llama-infra config  →  💰 Energy cost      (global: currency, master toggle)
/llama-infra config  →  🌐 Servers → machine → 💰 Energy cost   (per machine)
- Currency (global) — USD, EUR, GBP or CNY. It only changes the display unit; tariffs are stored per kWh in that currency.
- Per-server power draw & tariff — the power draw belongs to the machine, so each server gets its own profile inside its own config menu (
🌐 Servers→ select the machine →💰 Energy cost; adding a new server asks for it right away). SetkWduring inference (e.g.0.15for 150 W — GPU TDP + idle draw is a good approximation) and the electricity price per kWh. All models served by that machine inherit it.
Once set, each provider request is timed (before_provider_request → assistant message_end, partial/aborted requests included) and charged. The footer shows the session total as 💰 (e.g. 💰3.2c = 3.2 euro-cents; ¢/c/p/分 per currency); enable/disable anytime from the same menu.
Parallel agents & accuracy — when several clients hammer the same server in parallel, each client's wall time is the server time it actually consumed (decode is interleaved), so the session total approximates the machine's inference energy. Good for cost visibility; not a metering-grade measurement.
Config lives in ~/.pi/agent/llama-infra.json:
{
  "servers": [
    { "id": "local", "host": "127.0.0.1", "ports": [8000, 8080, 8081], "enabled": true,
      "costProfile": { "kW": 0.15, "ratePerKwh": 0.21, "label": "bruma 27B" } }
  ],
  "settings": { "currency": "eur", "costTracking": true }
}
Architecture
llama-infra/
├── package.json         # pi package manifest (pi-package)
├── LICENSE              # MIT
├── README.md
└── src/
    ├── index.ts         # Entrypoint: hooks, command, lifecycle. Statically imports core + types.
    ├── core.ts          # Config persistence, shared state, id helpers, compat profile (loaded at startup).
    ├── types.ts         # Shared interfaces (type-only; erased at runtime).
    ├── scan.ts          # Discovery engine (lazy: HTTP probing, /props, halogen /health context graft, LM Studio catalog, /proc, kind detection).
    ├── registration.ts  # Scan → pi-model mapping + provider registration (lazy).
    ├── metrics.ts       # Server /metrics poller → ServerMetricsState (lazy; only if `metricsEnabled`).
    ├── speed.ts         # Client-side speed tracker + footer status line (lazy; only if `metricsEnabled`).
    ├── cost.ts          # Cost profiles, currency formatting, energy math (static import; tiny).
    ├── cost-tracker.ts  # Energy-cost tracker: times requests, accumulates, feeds usage.cost (static).
    ├── ui.ts            # /llama-infra subcommands, menus, status, help (lazy).
    └── prompt-warmup.ts # Header warmup: capture + cache system prompt KV (lazy; only if `warmup`).
Module load profile:
| Module | Loaded when | Approx. size |
|---|---|---|
index.ts + core.ts (+ types.ts) |
Startup (static) | ~25 KB |
scan.ts + registration.ts |
First discovery (dynamic) | ~27 KB |
prompt-warmup.ts |
Primed at load if warmup enabled; not loaded when disabled |
~15 KB; skipped entirely when warmup is OFF |
metrics.ts + speed.ts |
Primed at load if metricsEnabled; not loaded when disabled |
~18 KB; skipped entirely when metricsEnabled is OFF |
cost.ts + cost-tracker.ts |
Static at load (tiny; needed in sub-agent processes too, which never fire session_start) |
~4 KB |
ui.ts |
First /llama-infra … command (dynamic) |
~32 KB |
Zero external npm dependencies (only pi's bundled @earendil-works/pi-coding-agent + Node built-ins).
Subsystems:
- Discovery engine — multi-server probing with timeouts, retry budgets, and per-server kind detection (llama.cpp, ZINC, DwarfStar, lucebox, LM Studio, vLLM, halogen)
- Router support — single-model and multi-model llama.cpp modes with per-model status, args parsing and metadata extraction
- Speed & metrics subsystem — client-side per-token speed measurement (prefill + moving-window generation), throttled footer status updates, and server
/metricspolling that supplements the footer while the client is idle - Thinking budgets — per-model per-level configuration with automatic
reasoningregistration - Config persistence —
~/.pi/agent/llama-infra.jsonwith one-time migration fromlocal-models.json - /proc scanner — local llama-server process detection for vision, KV cache quant, and drafter flags
Migration from local-models
If you have an existing ~/.pi/agent/local-models.json, llama-infra migrates it automatically on first run — your servers and settings are preserved. The old local-models extension can be removed after migration.
License
MIT © Javier Noguerol