pi-llama-server
Pi extension for llama-server router - model discovery, auto-load, per-project config
Package details
Install pi-llama-server from npm and Pi will load the resources declared by the package manifest.
$ pi install npm:pi-llama-server- Package
pi-llama-server- Version
1.2.0- Published
- Oct 15, 2026
- Downloads
- 338/mo · 123/wk
- Author
- am17an
- License
- MIT
- Types
- extension
- Size
- 2.6 MB
- Dependencies
- 0 dependencies · 1 peer
Pi manifest JSON
{
  "extensions": [
    "./extensions/llama-server.ts"
  ]
}
Security note
Pi packages can execute code and influence agent behavior. Review the source before installing third-party packages.
README
Note: This is how I use pi.dev + llama.cpp on my local machine. I created a plugin so that I can update my setup quickly.
pi-llama-server
Pi extension that integrates a running llama-server instance with the Pi Coding Agent. Discovers llama-server models and automatically loads the selected model when you switch models in Pi.
Demo
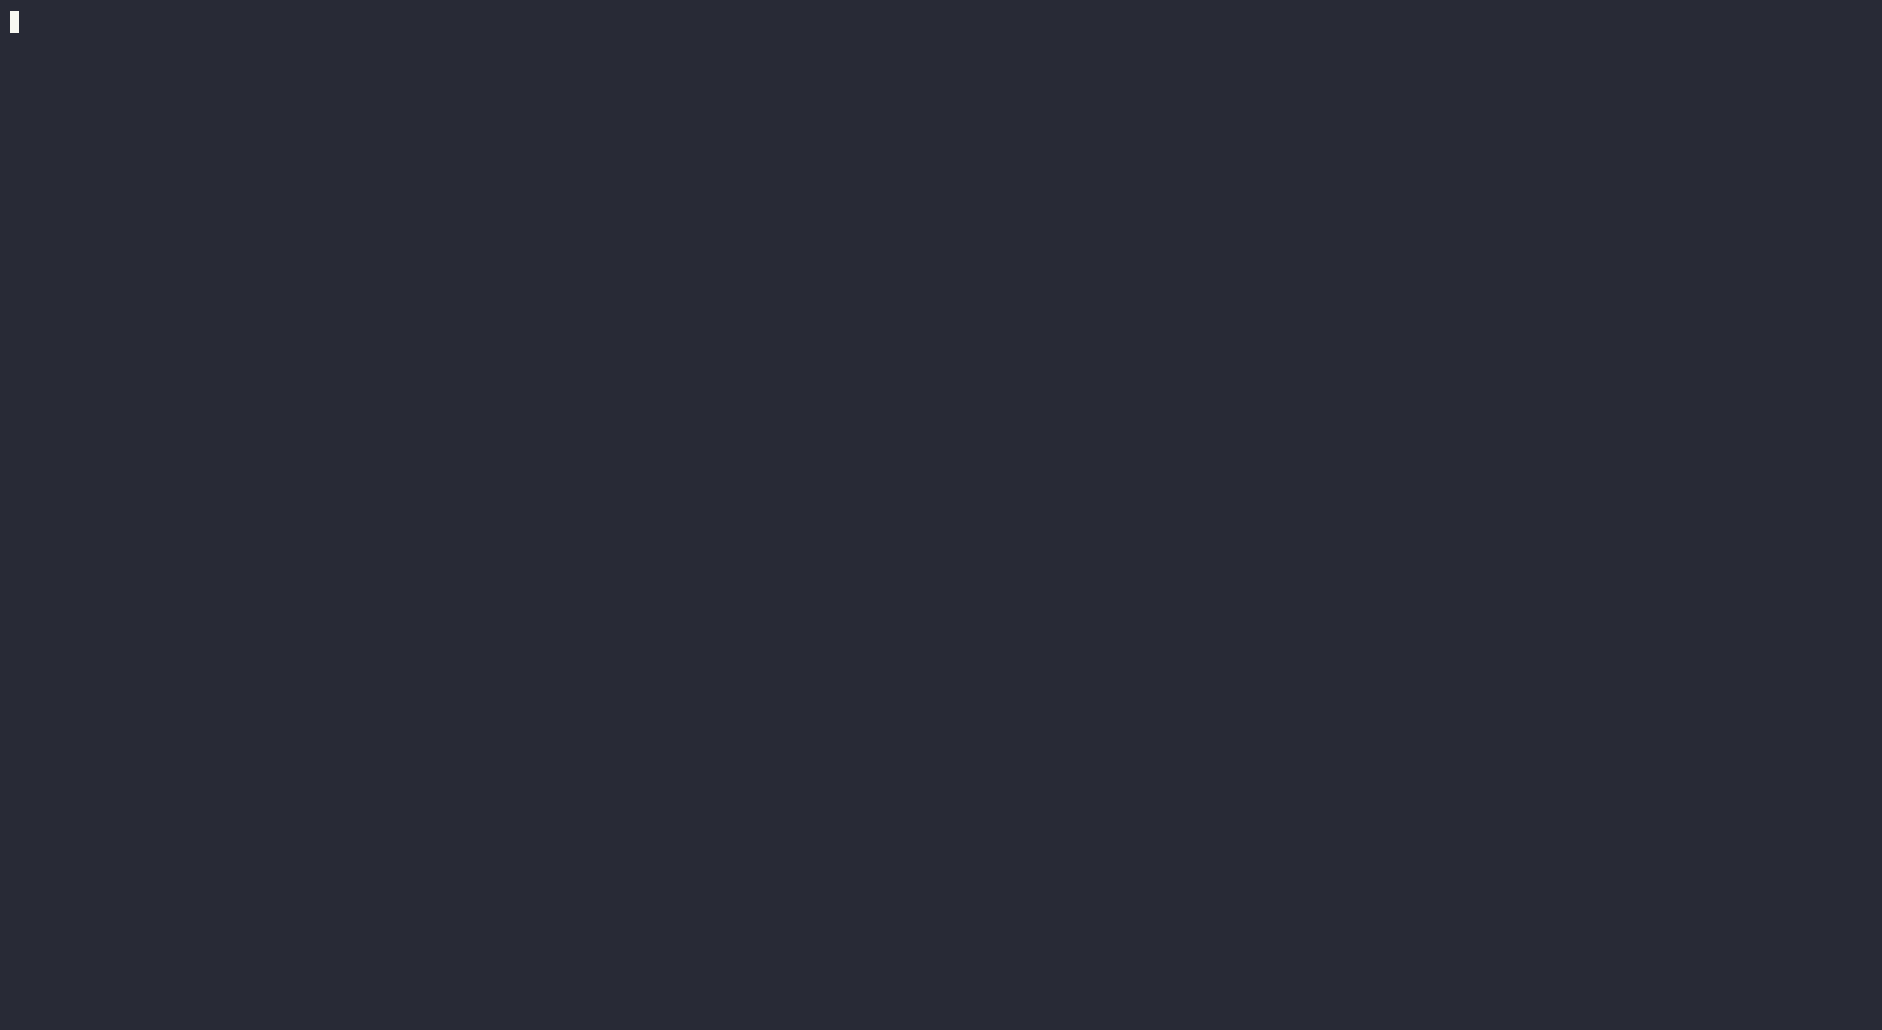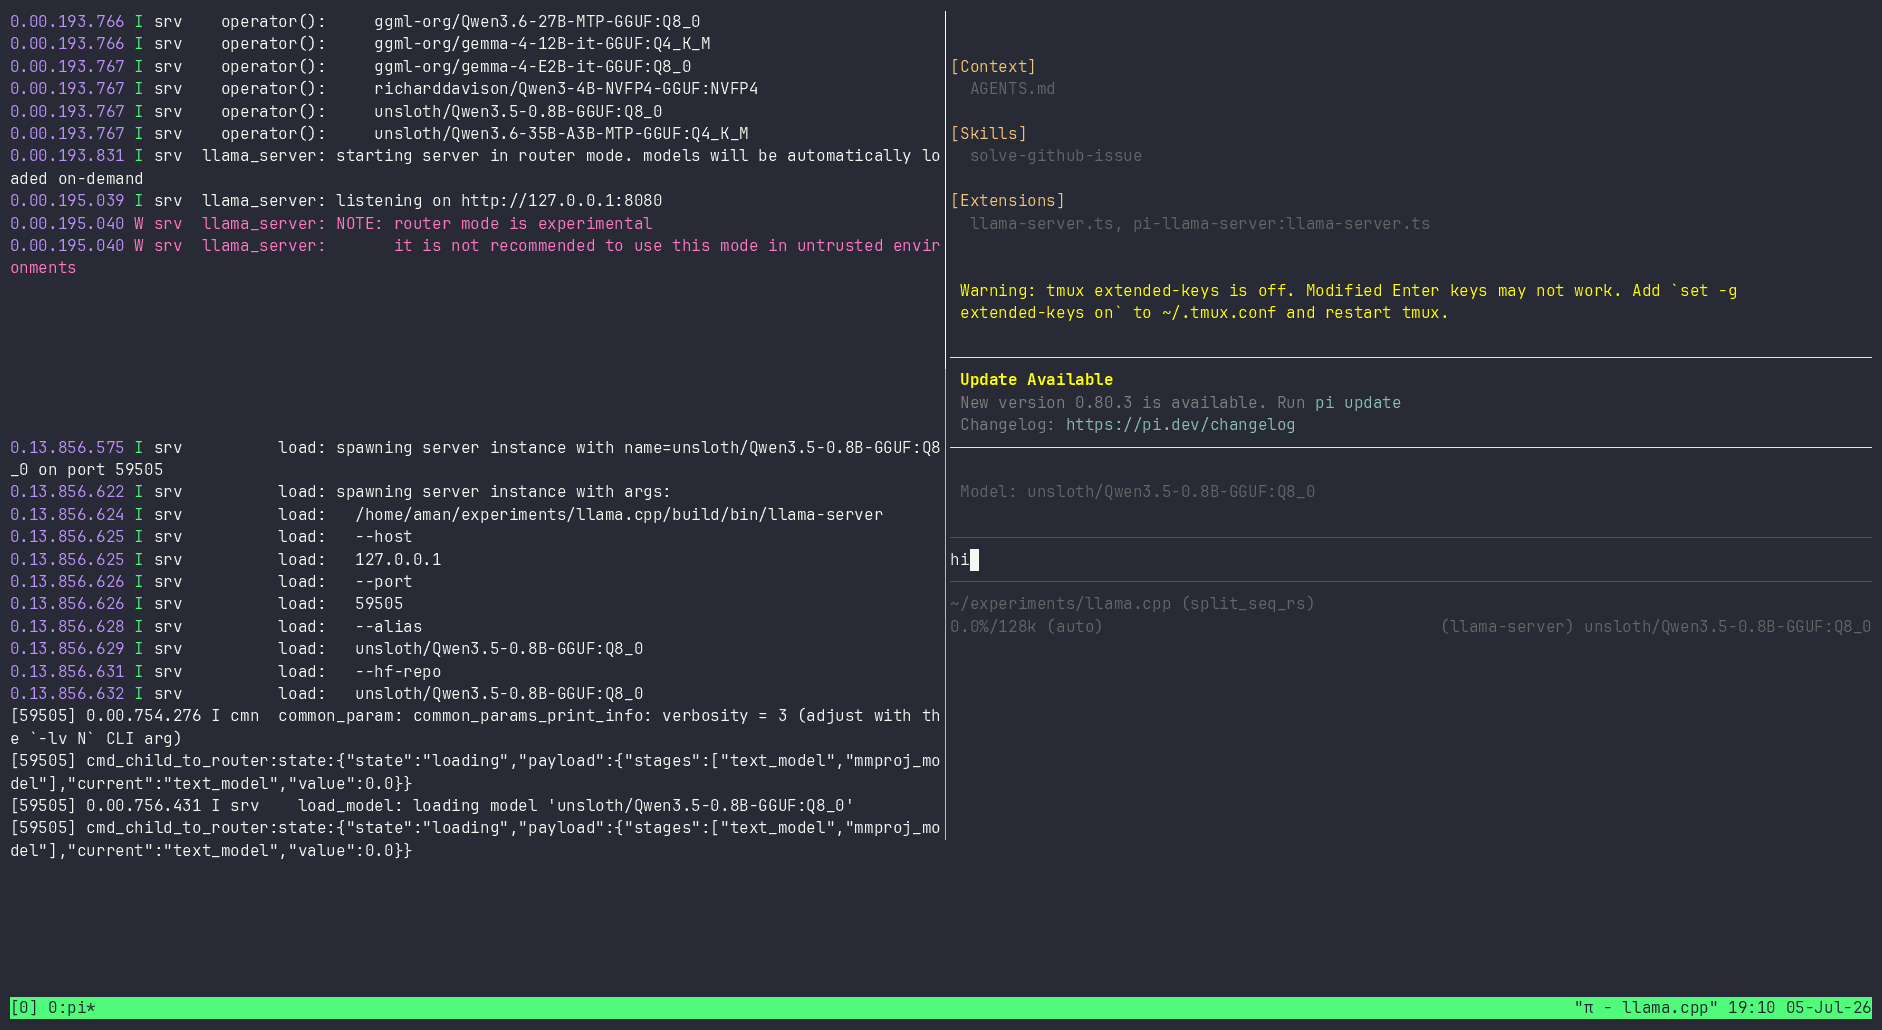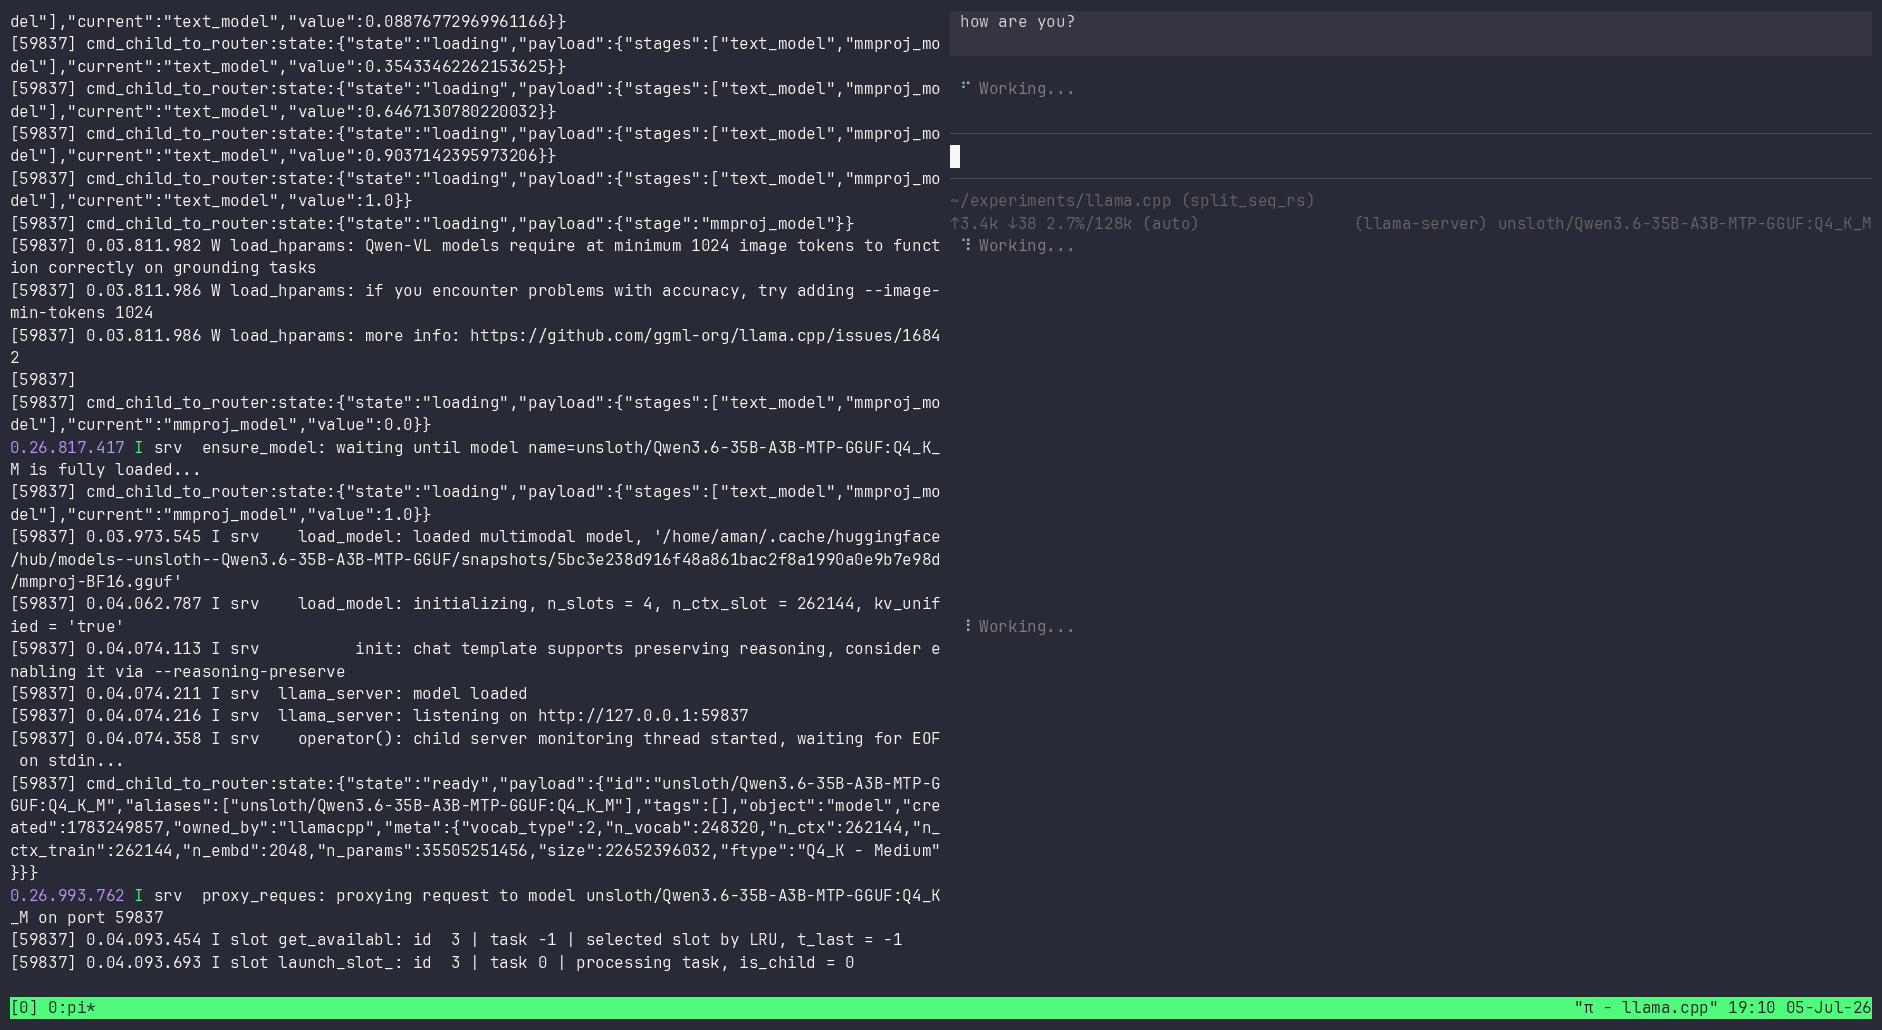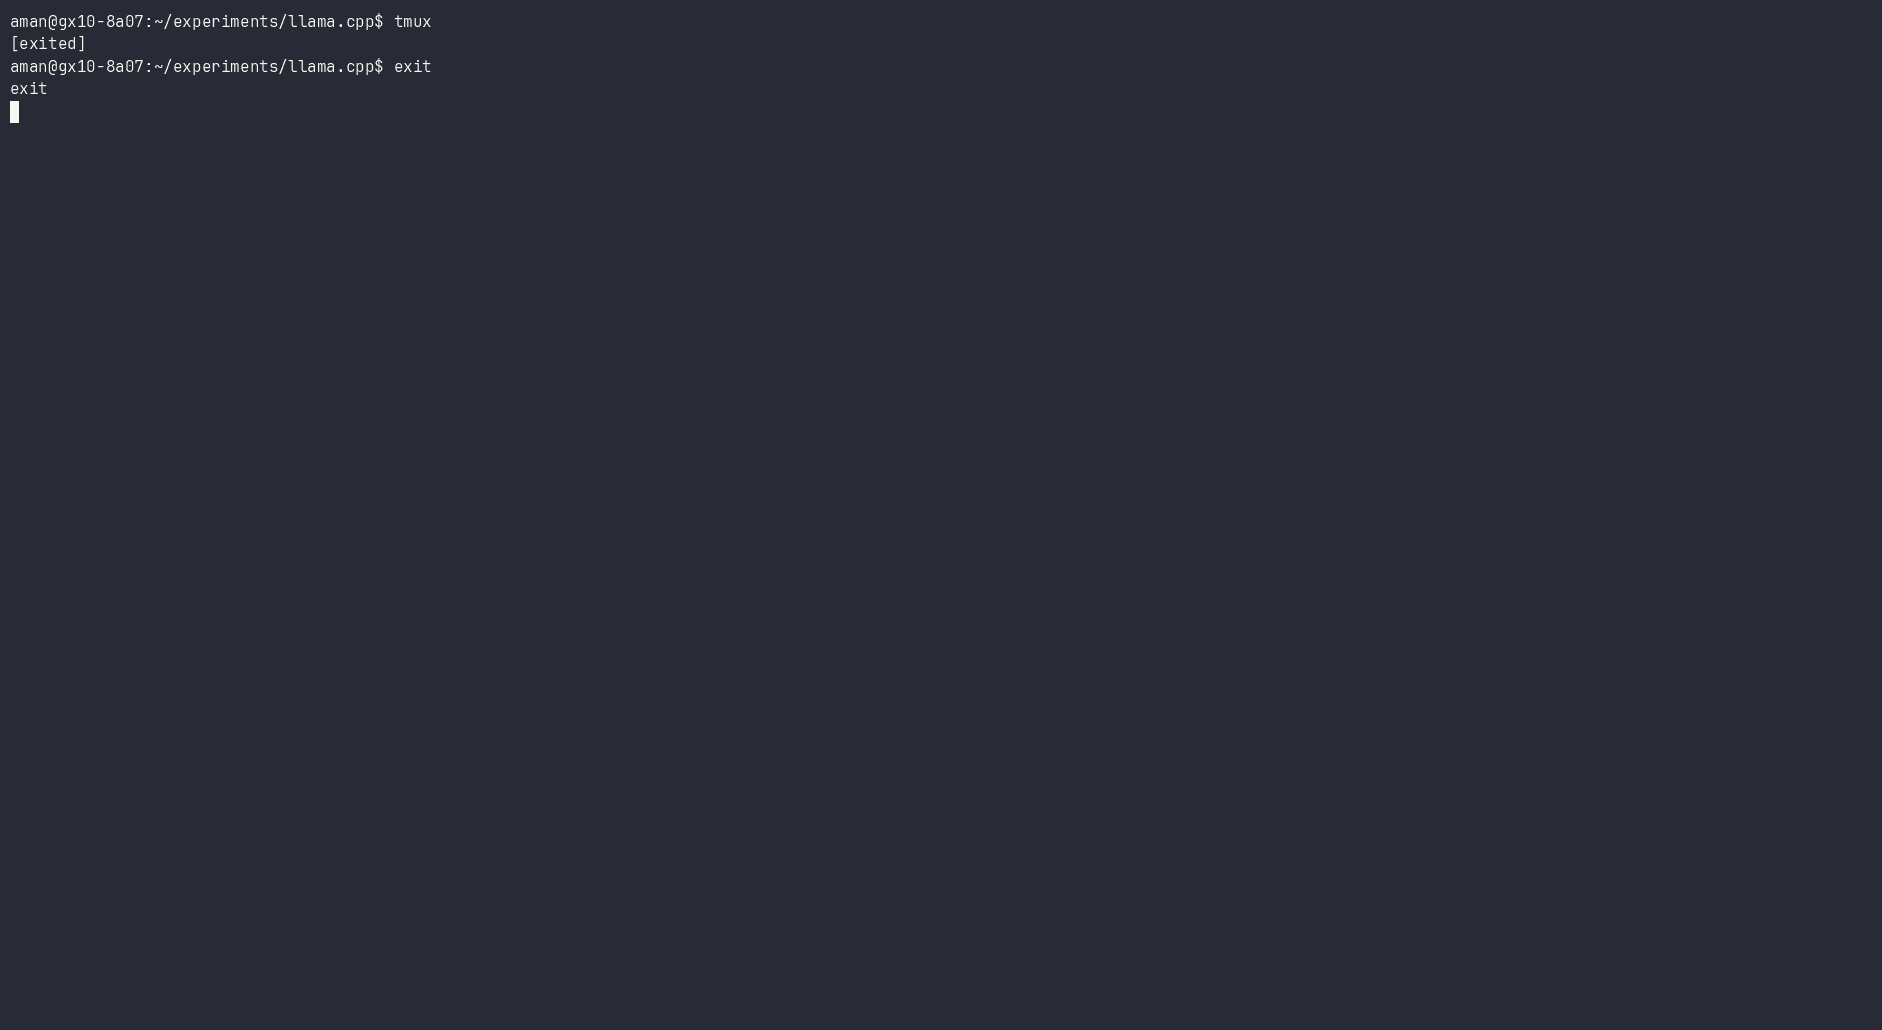
Prerequisites
- A running llama-server instance (from llama.cpp) in
router-mode(the default if you don't mention-m) - Pi Coding Agent installed (
@earendil-works/pi-coding-agent)
Install
pi install npm:pi-llama-serverOr from git:
pi install git:github.com/user/pi-llama-serverPi auto-discovers the extension via pi.extensions in package.json. No additional setup needed.
Configuration
The llama-server URL is resolved in this order:
- Per-project config — create
.pi/llama-server.jsonin your project root:{ "url": "http://10.0.0.5:9090" } - Environment variable — set globally:
export LLAMA_SERVER_URL=http://10.0.0.5:9090 - Default — falls back to
http://127.0.0.1:9931
API Key (optional)
If your llama-server endpoint requires authentication, set an API key:
- Per-project config — add
apiKeyto.pi/llama-server.json:{ "url": "http://10.0.0.5:9090", "apiKey": "your-api-key" } - Environment variable:
export LLAMA_SERVER_API_KEY=your-api-key
The API key is sent as a Bearer token on all requests to the server.
Usage
Use Ctrl+P (or /model) in Pi to select any llama-server model for inference. Pi switches to that model, and the extension automatically tells llama-server to load it. While llama-server reports loading progress, Pi shows a progress bar in the footer status.
After each llama-server response, the footer also shows the speed of that request:
PP 965.1 t/s (465 tok) · TG 134.0 t/s (89 tok)- PP (prefill / prompt processing): uncached prompt tokens divided by the time from sending the request to the first streamed token. Prompt tokens served from llama-server's cache are not counted.
- TG (token generation): output tokens after the first, divided by the time from the first to the last streamed token.
Both are measured on the client as the response streams in. TG closely matches llama-server's own predicted_per_second. PP also includes per-request overhead (chat templating, tokenization, HTTP), so on short prompts it reads well below llama-server's prompt_per_second; the gap shrinks as prompts grow.
How it works
When Pi starts, the extension:
- Resolves the llama-server URL from config/env/default
- Queries
GET /modelsto discover available GGUF models - Registers each model as an OpenAI-compatible provider under
{url}/v1 - Listens for model switch events and calls
POST /models/loadon the server - Listens to
GET /models/ssewhile a selected model is loading to show footer progress
llama-server endpoints used
| Endpoint | Method | Purpose |
|---|---|---|
/models |
GET | List all models |
/models/load |
POST | Load a model |
/models/sse |
GET | Stream model status/progress events |
/v1/... |
POST | OpenAI-compatible completions (via Pi provider) |