pi-webfind
Claude Code-style web research for the pi coding agent — WebSearch, query-aware fetch (PDFs, Wayback, site adapters, markdown extraction), Stack Overflow, GitHub, HN, Wikipedia, npm. 100% free, no API keys.
Package details
Install pi-webfind from npm and Pi will load the resources declared by the package manifest.
$ pi install npm:pi-webfind- Package
pi-webfind- Version
0.6.0- Published
- Sep 5, 2026
- Downloads
- 614/mo · 230/wk
- Author
- jawwadzafar
- License
- MIT
- Types
- theme
- Size
- 181.3 KB
- Dependencies
- 0 dependencies · 2 peers
Pi manifest JSON
{
  "themes": [
    "./themes"
  ]
}
Security note
Pi packages can execute code and influence agent behavior. Review the source before installing third-party packages.
README
Install
pi install npm:pi-webfind
or straight from GitHub:
pi install git:github.com/jawwadzafar/pi-webfind
What it does
Same muscle memory as Claude Code's WebSearch — ⏺ Web Search("query")
headers, live status, ✓ 8 results · ddg+brave · 2.1s, expandable rows,
document reading, grouped synthesis. No cost, no keys.
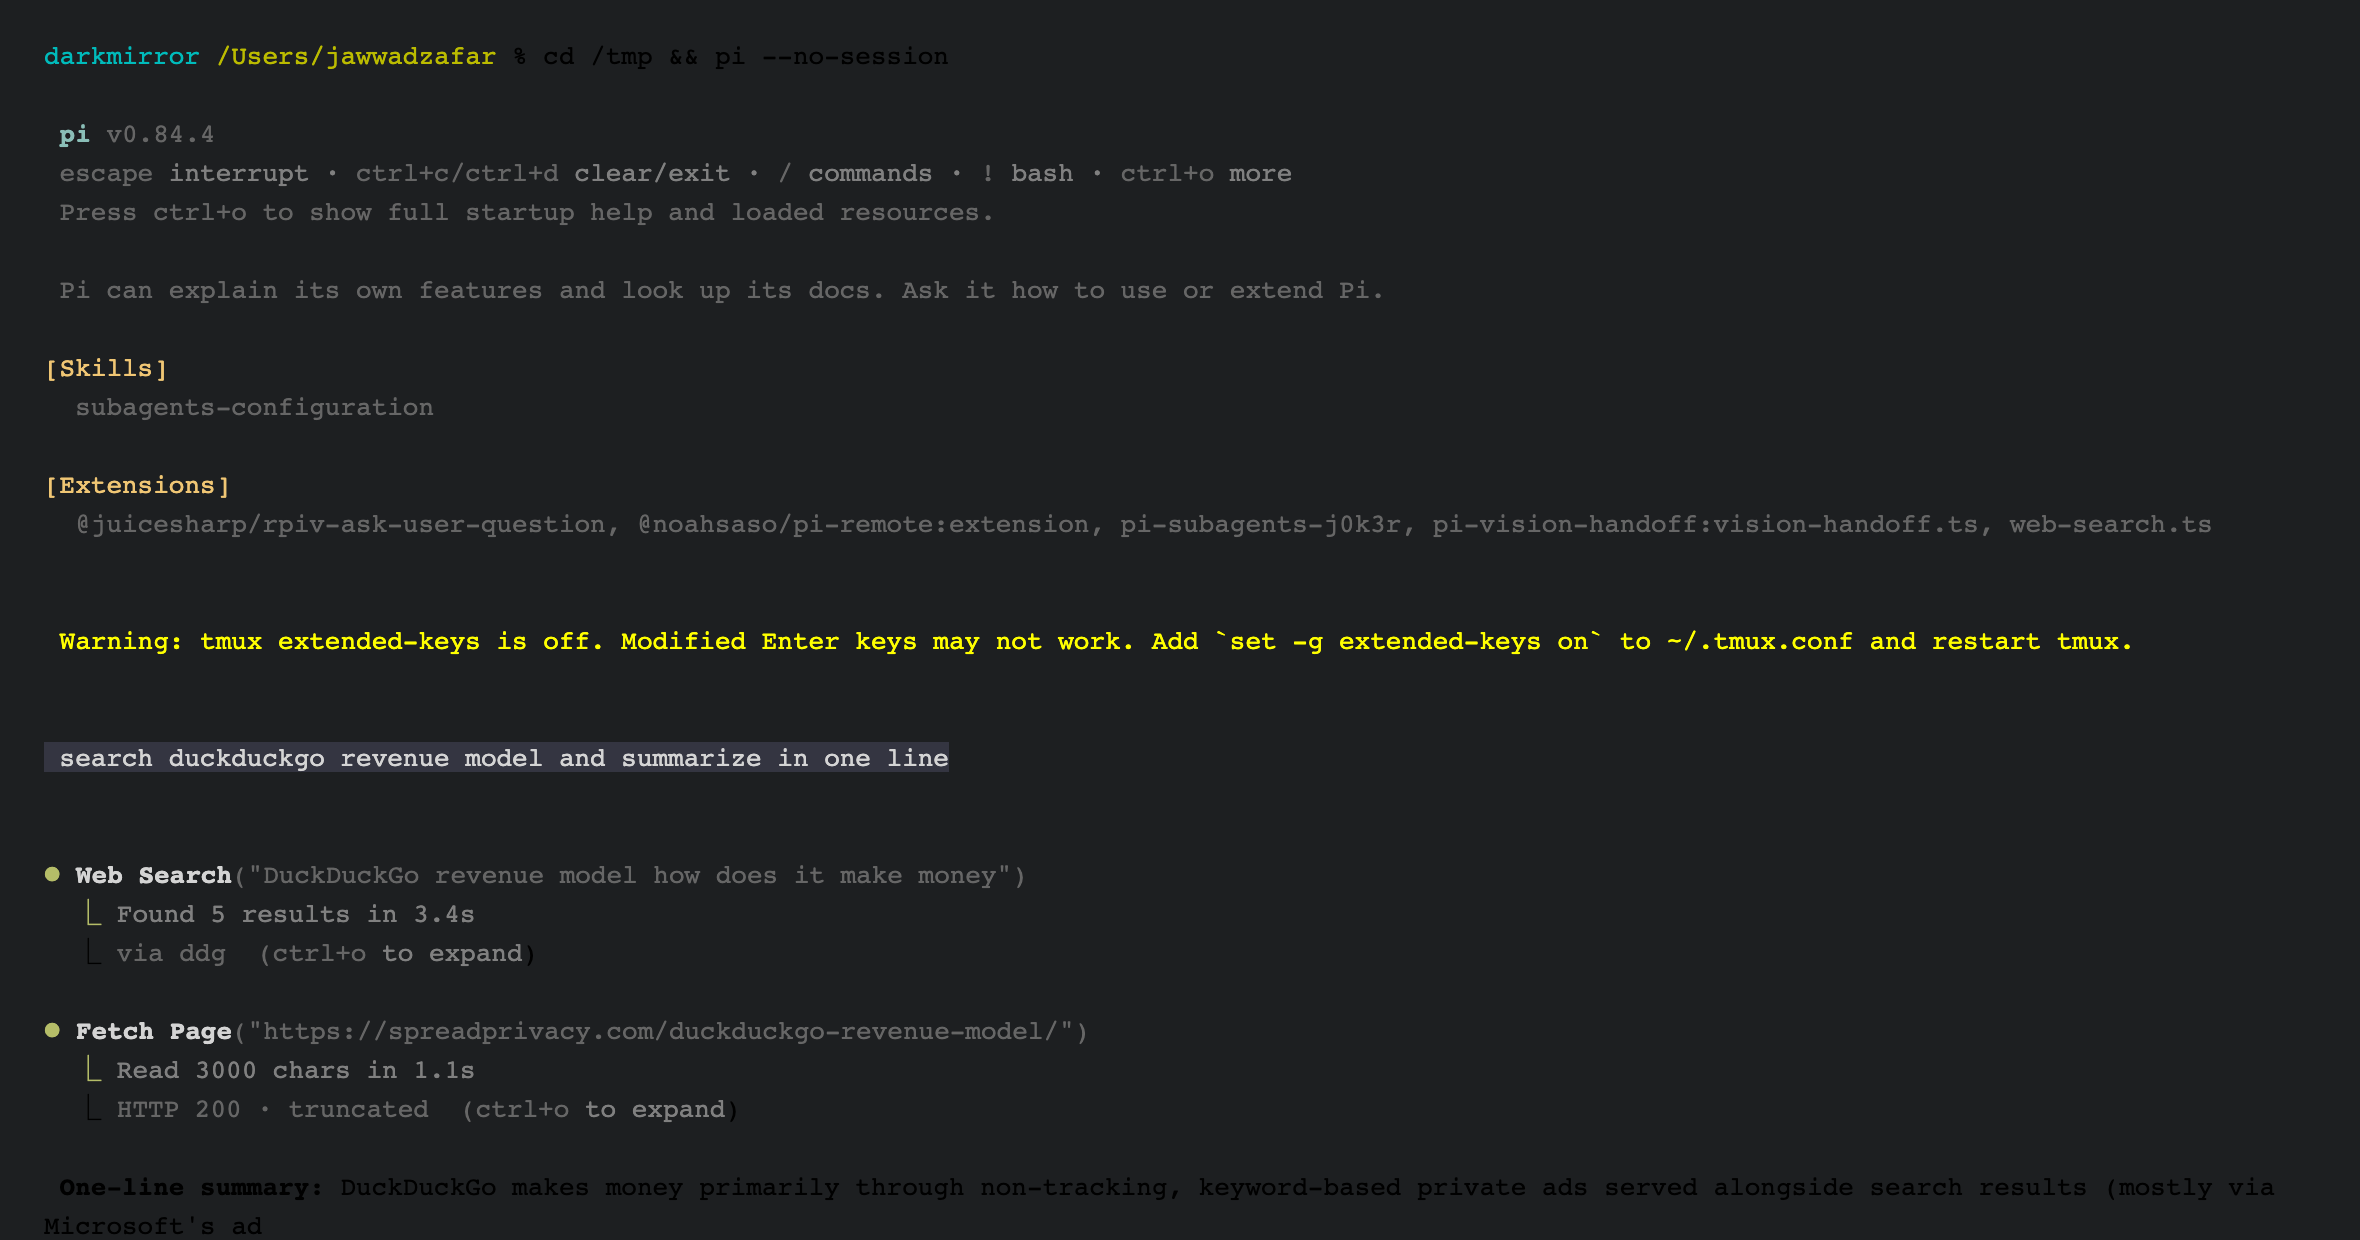
7 tools + 1 command:
| Tool | Best for |
|---|---|
web_search |
news, articles, broad queries — DuckDuckGo + Brave + Bing RSS, RRF-fused |
fetch_page |
read any URL — HTML/PDF/JSON, query-aware passages, bot-wall busting |
search_stackoverflow |
error messages, debugging |
search_wikipedia |
definitions, concepts, history |
search_npm |
JS/TS packages with quality scores |
search_github |
repos, stars, languages |
search_hn |
tech community opinion, launches |
/research <topic> |
parallel multi-source research → grouped briefing |
Reading comprehension, not just fetching
fetch_pagewithquery— returns the intro plus the most query-relevant passages (BM25, heading trails), not the first 8,000 characters. The difference between an infobox dump and the two paragraphs that answer you.web_searchwithdeep: true— reads the top results in parallel and attaches a query-relevant excerpt to every row. Factual questions often answer themselves without a single fetch.- Markdown extraction — density-scored article detection turns pages into
structured markdown; Wikipedia arrives as prose, not
{{cite web}}soup. - Site adapters — GitHub repos/issues/PRs/files, Stack Overflow, HN,
Reddit and Wikipedia skip scraping entirely and come from their clean free
APIs. The output header tells you which served you (
github-issue-api,stackexchange-api, …).
When engines fight back
Every search and fetch walks a fallback ladder before admitting failure:
web_search   DDG html → lite → POST → r.jina.ai proxy → Bing RSS
             → engine "multi": DDG ∥ Brave ∥ Bing in parallel, RRF-fused
             → any primary failure auto-retries via multi

fetch_page   site adapter (GitHub/SE/HN/Reddit/Wikipedia APIs)
             → direct fetch (browser UA, 3× backoff)
             → 401/403/429/503 → Wayback Machine snapshot
             → thin/SPA page → r.jina.ai headless render
             → block-page detection (never shows fake content as success)
Disk-backed caches (~/.pi/agent/cache/webfind/) survive restarts: 10-min
search, 1-h fetch. refresh / no_cache flags skip them.
Security
pi-webfind runs with full system access like any pi extension. What it does with it:
- Outbound HTTPS only — search engines, public APIs, pages you fetch
- SSRF-guarded — localhost, private ranges and link-local addresses are blocked
- Never executes or writes fetched content; it reads URLs and returns text
- Politeness throttle per host; fake-browser UA only where required, honest
pi-webfind/x.yUA everywhere it matters - The only optional credentials are listed below. Everything else is keyless by design.
Optional accelerators (still fully free without them)
| Env var | Effect when set | Without it |
|---|---|---|
GITHUB_TOKEN |
Lifts GitHub API from 10 to ~30 req/min in site adapters | 10 req/min anonymous |
JINA_API_KEY |
Reader relay throttle 3.5 s → 300 ms; enables s.jina.ai search leg in engine:"multi" |
3.5 s gap, no jina search leg |
BRAVE_API_KEY |
Adds Brave's official JSON API as the first engine:"multi" attempt |
scraped Brave only |
TAVILY_API_KEY |
Adds Tavily as a engine:"multi" attempt |
no Tavily |
Every var is optional; with none set, behavior is identical to the baseline: keyless scraping with the fallback ladder. Keys are never required and never sent anywhere except their own API host.
Limits (be honest about free)
- Scraped engines tighten defenses anytime — the fallback ladder is the mitigation
- Unauthenticated GitHub is 10 req/min (see
GITHUB_TOKENabove) - Result dates appear only when engines provide them (DDG stamps, Bing pubDates)
- Public SearXNG instances rate-limit cloud IPs; jina proxy + Brave cover that gap
Docs
Full tool reference, parameters and guides at jawwadzafar.github.io/pi-webfind.
License
MIT